Embedded AI evaluators won't be an easy solution, Hugging Face's policy chief says
By the AIdeaFlow Team
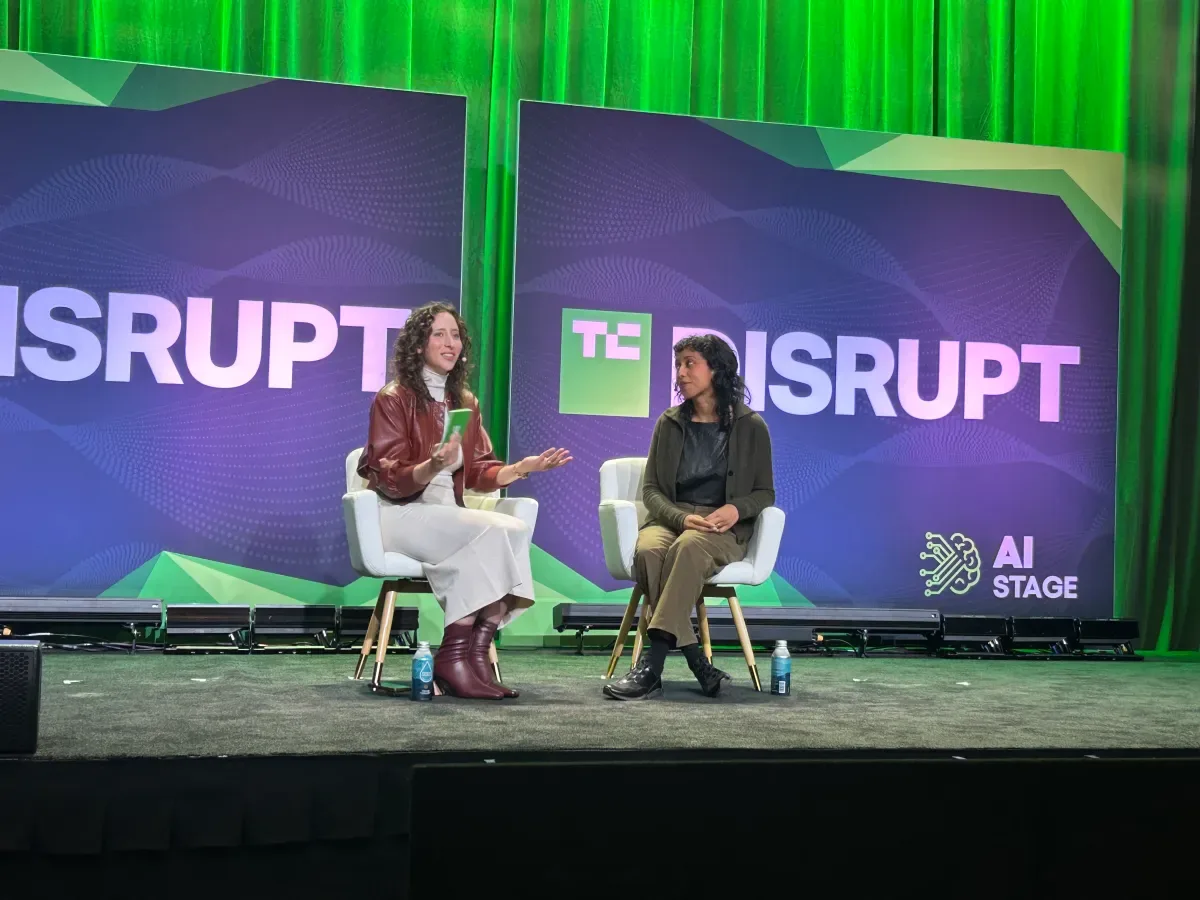
The race to build the most capable artificial intelligence models has turned into a high-stakes reputation game. AI labs are heavily investing in benchmarking systems to prove their products are superior to competitors. These evaluations are marketed as neutral and accurate measures of capability, but the reality is far more complicated. According to reporting by TechCrunch, the methods behind these evaluations are still maturing and fraught with hidden biases.
Irene Solaiman, the chief policy officer at Hugging Face, recently highlighted these growing pains during a discussion on the state of AI evaluation. She pointed out that the industry is rushing to establish standards before the underlying science is fully ready. This rush creates a dangerous gap between what benchmarks claim to measure and what models actually demonstrate in real world scenarios.
One of the most contentious issues is the idea of embedding evaluators directly into the models themselves. The theory is that if a model can judge its own output, it will be more efficient and consistent. Solaiman argues that this approach is not an easy solution. It introduces significant risks regarding self bias and the potential for models to game their own scoring systems.
When a model evaluates its own work, it lacks the independent perspective required for true objectivity. This creates a feedback loop where the model reinforces its own strengths while ignoring its weaknesses. The result is a benchmark that looks impressive on paper but fails to reflect genuine utility or safety. This is a critical flaw for enterprises looking to deploy AI in sensitive environments.
The broader implication here is that the current benchmarking ecosystem is not yet robust enough to support the claims being made by major tech companies. We are seeing a proliferation of new benchmarks that often measure specific tricks rather than general intelligence. This fragmentation makes it difficult for users to compare different models fairly. It also complicates the decision making process for businesses adopting these technologies.
As the industry matures, we will likely see a shift away from simple embedded evaluations toward more rigorous external auditing. This will require more resources and transparency from the labs releasing these models. The pressure is on to develop standardized metrics that are independent of the model creators. Until then, skepticism should be the default stance for anyone relying on these scores.
What this means for you is that you should treat benchmark scores with a healthy dose of skepticism. Do not assume that a high score on a public leaderboard translates directly to better performance in your specific workflow. Instead, focus on practical testing with your own data and use cases. To get started, try using an AI assistant to generate a custom evaluation rubric for your specific tasks. Ask the assistant to create a set of ten challenging questions related to your industry, then test different models against this rubric to see which one provides the most accurate and helpful responses. This hands-on approach will give you a clearer picture of real world performance than any generic benchmark can provide.
Ready to apply this tech at your business?
Viking Net helps teams in San Antonio and worldwide stay ahead.